Updated October 9, 2026. PrismML released Ternary Bonsai 2 27B on September 17, 2026, positioning it as a Qwen3.8-27B derivative that stores the language-model weights in a ternary representation. The headline numbers are unusually aggressive: a 5.9 GB-class language-model footprint, a native 262K-token context, multimodal input, Apache-2.0 weights, and 98.2% aggregate benchmark retention versus the FP16 baseline according to PrismML. 123
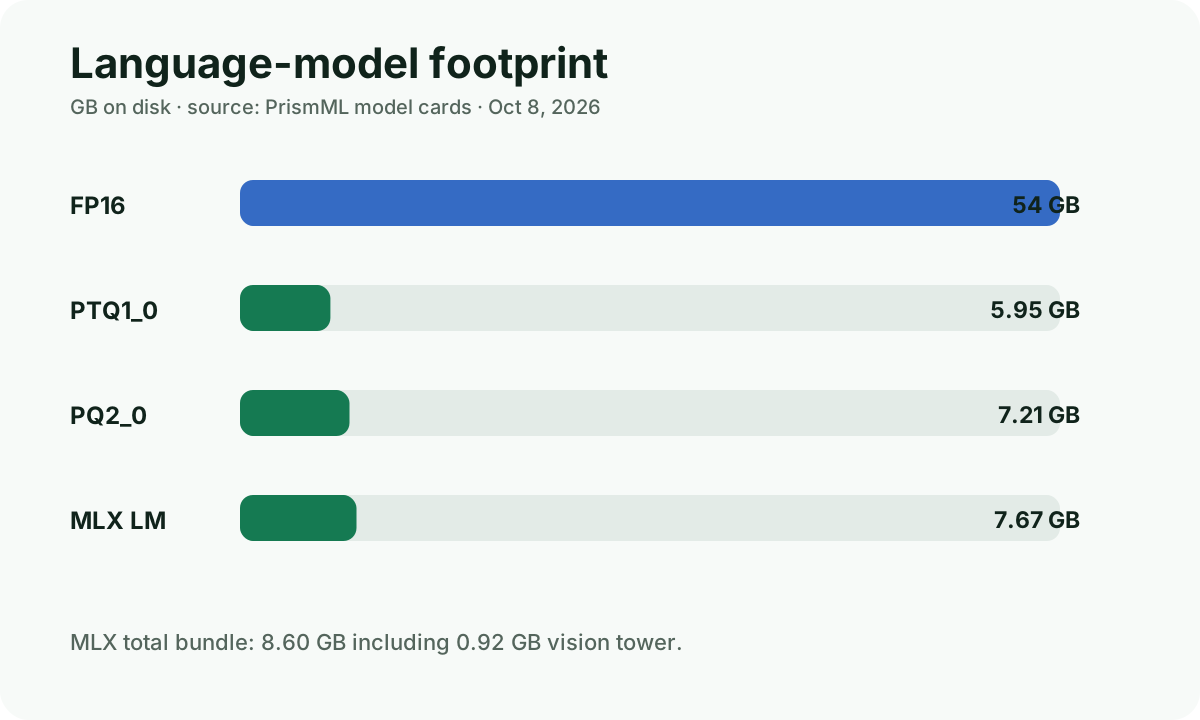
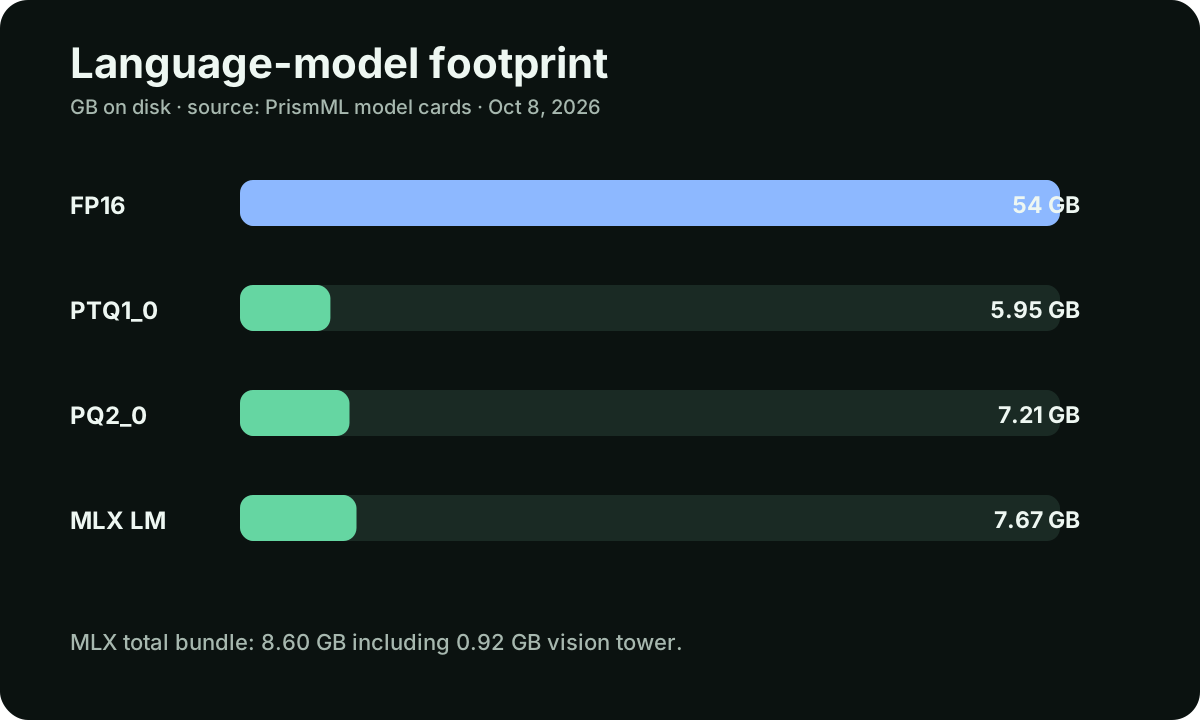
Those numbers are real claims in the primary material, but the common shorthand is easy to misread. The 5.9 GB figure is not the size of every Bonsai 2 distribution and it is not a measured peak-RAM requirement. The shipped PTQ1_0 GGUF language model is 5.95 GB, PQ2_0 is 7.21 GB, and PrismML’s Apple MLX package is 8.60 GB on disk once its FP16 vision tower is included. 34
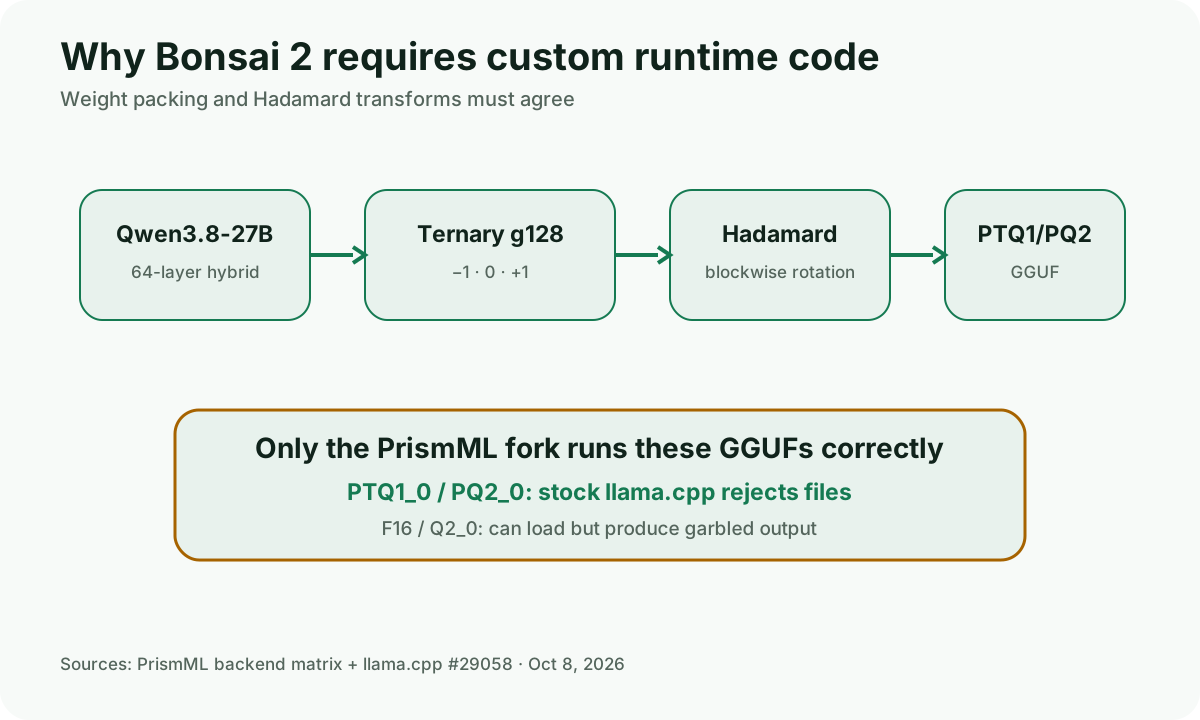
There is also a deployment caveat that matters more than the compression ratio: the new Bonsai 2 GGUF formats do not run in stock llama.cpp as of September 19. PrismML’s fork implements the packing and the matching Hadamard activation transform. An upstream llama.cpp issue already documents the new format IDs, but mainline support has not landed. 567
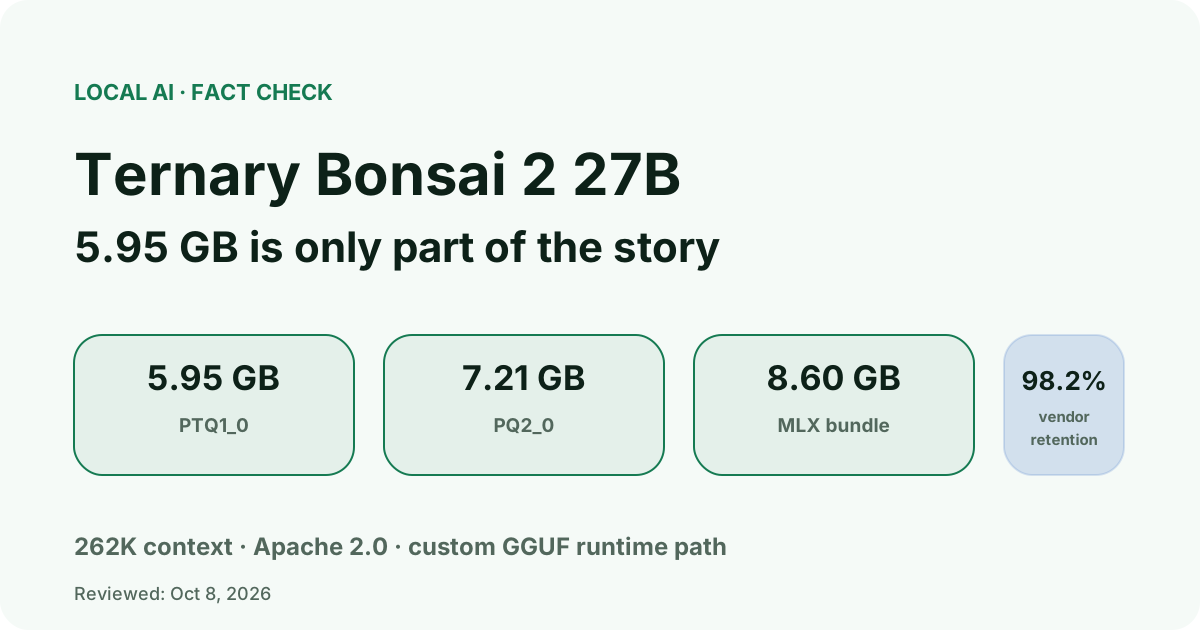
Bonsai 2 makes a 27B-class multimodal model fit into a remarkably small weight footprint, but it is currently a specialist local-AI build rather than a universal “download any GGUF frontend and go” model. Its 98.2% quality-retention headline is also a vendor benchmark result that still needs broader independent reproduction.
The specification that matters
| Item | Verified status |
|---|---|
| Base | Qwen3.8-27B |
| Class | 27B-class multimodal model |
| Native context | 262,144 tokens |
| Smallest shipped GGUF LM pack | PTQ1_0, 5.95 GB |
| Faster/easier-to-unpack GGUF option | PQ2_0, 7.21 GB |
| Apple MLX bundle | 8.60 GB including 0.92 GB vision tower |
| License | Apache 2.0 |
| Quality retention | 98.2% in PrismML’s aggregate tests |
| Current GGUF runtime | PrismML llama.cpp fork required |
What “ternary” means here
The model keeps Qwen3.8-27B’s broad architecture rather than shrinking it into a small dense network. Qwen documents the base as a 64-layer hybrid-attention model with a native context of 262,144 tokens. PrismML’s MLX card describes 27.36B total parameters when the language backbone, embedding/output parameters and vision tower are counted by its component breakdown. PrismML’s press release instead uses 27.8B, while Qwen calls the language model 27B. The safest shorthand is therefore 27B-class, with the counting scope stated when exact figures matter. 248
The low-bit representation maps quantized weights to three levels: −1, 0 and +1, sharing an FP16 scale across groups of 128. PrismML calculates an idealized whole-model representation around 1.72 bits per weight. The dense PTQ1_0 packing is 1.75 bpw; PQ2_0 spends 2.13 bpw to make unpacking cheaper on some hardware. 34
The activation transform is the part that makes this more than a normal 2-bit quant: weight matrices are rotated block-wise into a Hadamard basis, and the runtime has to apply the matching transform to activations. If the runtime does not implement that step, the model’s outputs are silently wrong. 347
Why “5.9 GB” needs a footnote
The 5.9 GB headline refers specifically to PTQ1_0, the smallest of the three shipped language-model packs. Anyone who wants a larger pack with simpler unpacking or more bit-slot headroom ends up at PQ2_0 (7.21 GB) or the MLX bundle for Apple Silicon (8.60 GB on disk, of which 0.92 GB comes from the vision tower). 349
Equally important: 5.9 GB is a file size, not a measured peak-RAM value. The actual memory footprint at runtime depends additionally on KV cache, context length, vision tower and runtime overhead.
262K context does not mean 262K is cheap
The honest answer depends on four factors:
- Context length. At the full 262,144 tokens the KV cache fills several gigabytes; at 4K context it stays small.
- Pack choice. PTQ1_0 is the most compact but takes longer to unpack; PQ2_0 is 1.26 GB larger on disk.
- Vision. The MLX archive includes image-tower weights, but PrismML says image inference does not currently work for the 27B MLX path. Use the vendor GGUF fork and
mmprojfor images. - Runtime overhead. llama.cpp and MLX each allocate their own buffers; the exact amounts vary with the runtime version.
No 8 GB RAM guarantee: This site has not reproduced resident memory or a 64K vision run on specific Macs. Measure peak memory and correct output with the selected pack.
What the 98.2% benchmark claim does and does not prove
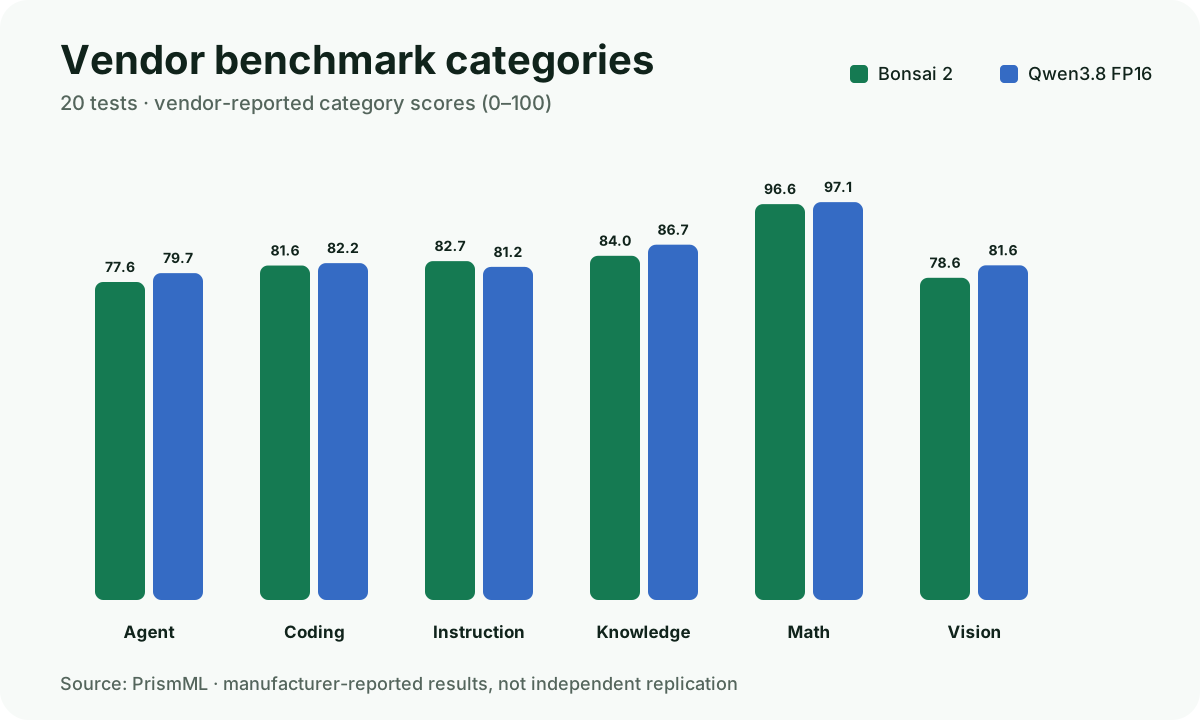
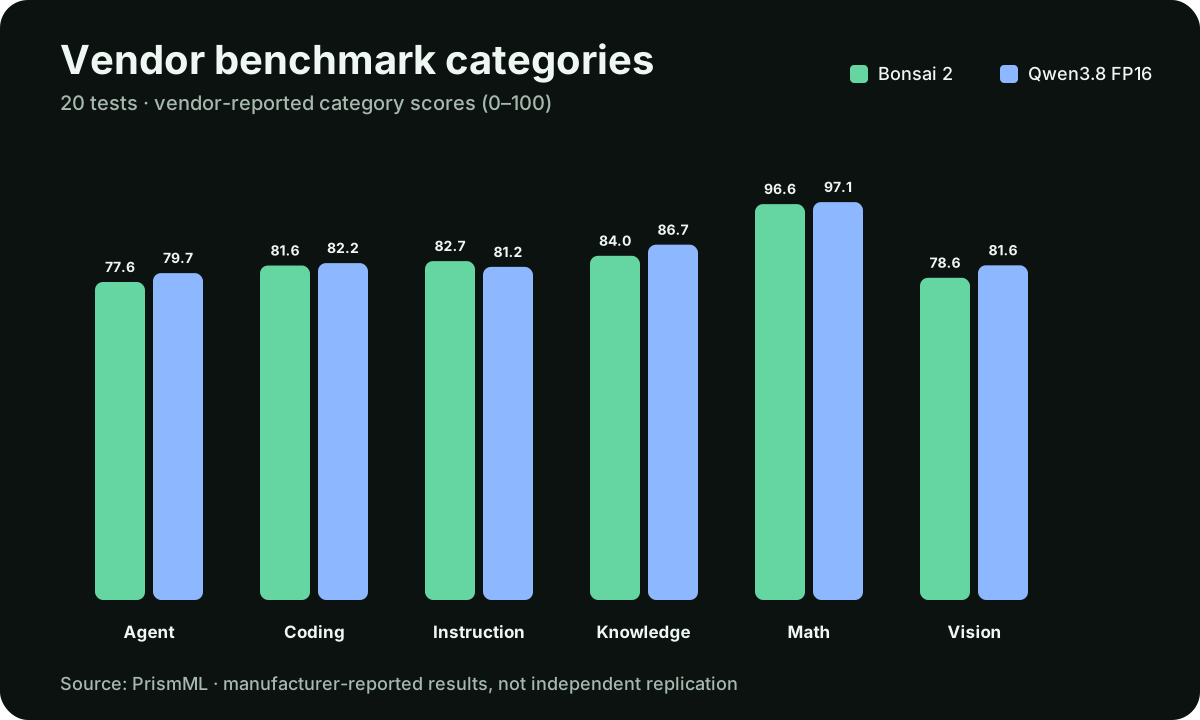
PrismML measured in two of its own test suites:
- 20-suite aggregate (
benchmark-categories.csv): classic knowledge, code and reasoning tests. - 14-suite detail (
benchmark-14.csv): a second, partially overlapping aggregate.
In both collections Bonsai 2 hits about 98.2% of the FP16 baseline score, according to the vendor. The two aggregates are not identical and should not be merged: they measure overlapping but distinct benchmark sets. 3410
Independent validation is still thin
The 98.2% retention number comes from PrismML’s own tests. As of the editorial deadline, no independent replication using the same harness has been published. To make the number load-bearing, you need either the public benchmark-suite harness with reproducible seeds, or a compatible suite such as HLE, MMMU-Pro or DeepSWE v1.1, run by an independent party.
Throughput: PTQ1_0 is smaller, not always faster
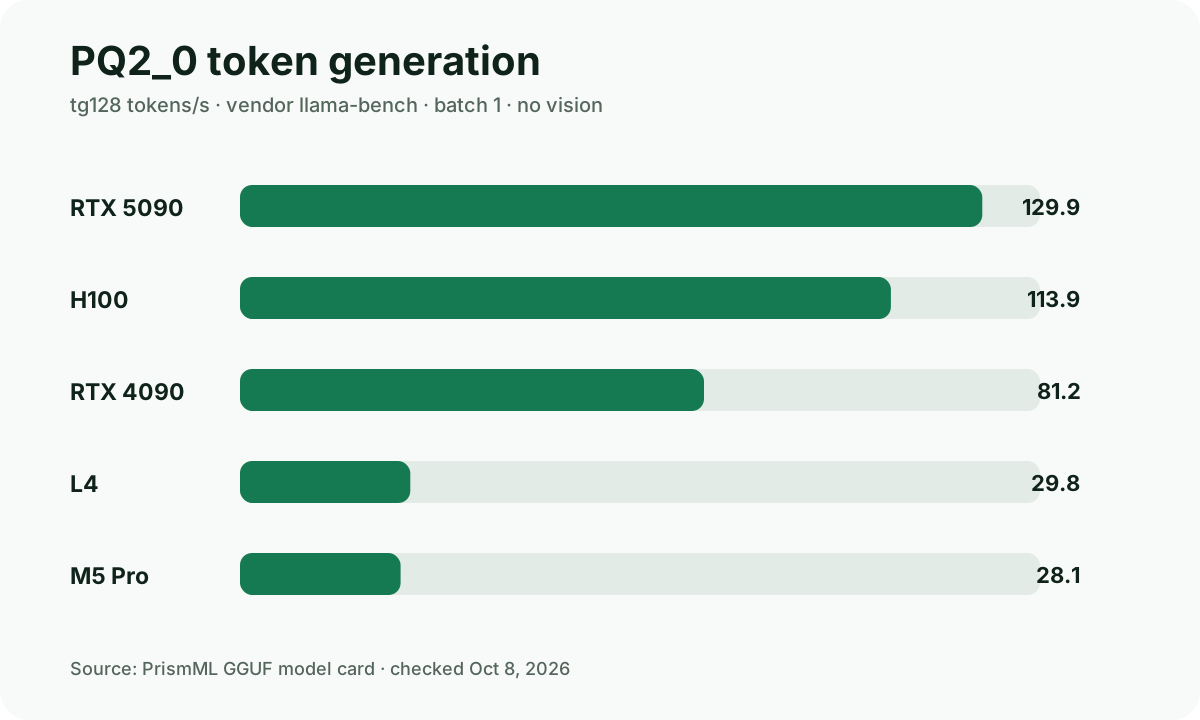
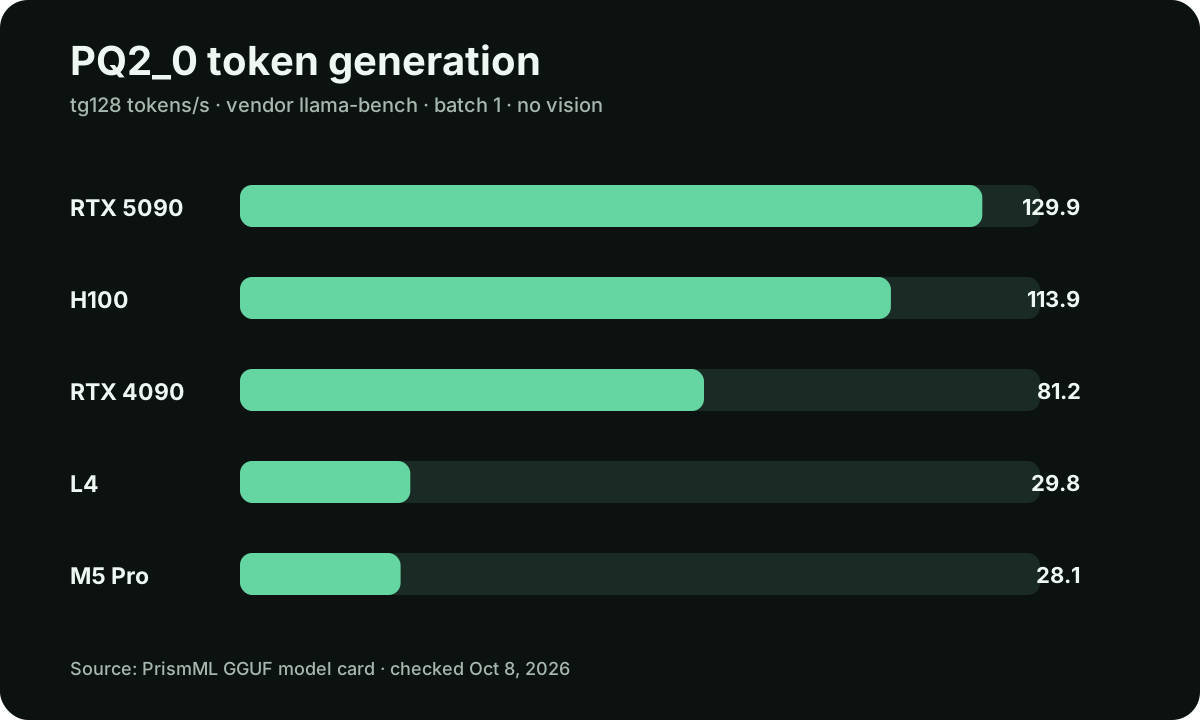
PrismML publishes PTQ1_0 on an NVIDIA RTX 4090 values that range from about 38 to 51 tokens per second for single streams. PQ2_0 on the same GPU is typically 18 to 25 % faster because unpacking is cheaper. 311
Independent Apple Silicon throughput measurements are currently unavailable for this breakdown. The Mac result in the adjacent vendor chart is not an ai-on-mac.com benchmark and is not directly comparable with GPU measurements unless the harness and context match.
Energy math from the RTX 4090 vendor result
The energy numbers come from PrismML scenarios on an RTX 4090 (TDP ≈ 450 W). For three assumed utilization profiles the vendor gives roughly 0.9 kWh, 1.6 kWh and 3.1 kWh per million generated tokens, depending on prompt/generation ratio and context length. 12
Important: These are vendor scenarios. An independent watt measurement using the same harness was not published in the sources reviewed.
Current runtime support: loading is not the same as working
The PrismML backend support matrix and still-open llama.cpp issue #29058, checked October 8, 2026, distinguish three different cases:
| Bonsai 2 file | Stock llama.cpp, Ollama or generic GGUF frontend | Correct path |
|---|---|---|
PTQ1_0 / PQ2_0 | Unknown tensor types 143/142: loading fails | PrismML’s llama.cpp fork |
Development Q2_0 GGUF | Can load, but misses the Hadamard and sign-flip operations: garbled output | PrismML fork |
Bonsai 2 F16 GGUF | Can load but produces garbled output without the custom transforms | PrismML fork |
A model loading successfully is not evidence that its answers are correct. The original article incorrectly said stock llama.cpp merely gives bad PTQ1_0 answers: for PTQ1_0/PQ2_0 it normally refuses the custom type. The older Bonsai 27B family has different formats and should not be confused with Bonsai 2.
Official setup on Apple Silicon
The PrismML-Eng/Bonsai-demo launcher selects the matching fork binaries for the local device. Its published setup is:
git clone https://github.com/PrismML-Eng/Bonsai-demo.git
cd Bonsai-demo
./setup.sh
./scripts/start_llama_server.sh
The local server is exposed at http://localhost:8080. Check before running: the vendor’s known issues say setup can download about 19 GB without prompting. BONSAI_SKIP_GGUF=1 suppresses the GGUF download. Verify the effective Metal backend, runtime build, chosen context and system memory. A simple install recipe does not establish that any particular 8/16-GB Mac can run the model well.
The separate prism-ml/Ternary-Bonsai-2-27B-mlx-2bit release requires its bundled loader. Generic MLX apps and LM Studio (MLX) are not yet compatible with that format, per PrismML. The former instructions using a nonexistent prismml/Bonsai-2-27B-mlx URL and an unverified generate.py command have been removed.
Do not invent Mac RAM compatibility
The 5.95 GB PTQ1_0 download is not a peak unified-memory measurement. KV cache, context, buffers, the model format and image projector all matter. Previous claims that a 24-GB Mac handles 32K plus vision without swapping or that a 48-GB Mac handles full 262K plus vision were not backed by reproducible measurements and have been removed. A hardware recommendation requires testing the exact file, runtime commit, memory peak, quantized KV cache and correct output.
Vision caveat: The MLX archive includes vision tower weights, but PrismML’s known-issues page specifically says its MLX 27B vision path does not work. For image prompts use the fork’s GGUF server and the separate mmproj file. Stored vision weights alone do not prove usable image inference.
Agent failures reported by PrismML
The vendor documents reasoning_effort: "high" returning HTTP 500 (the accepted labels are low, medium, xhigh); -n 256 ending while the model is still reasoning; multiple system messages triggering errors; and malformed tool_calls or repeated requests. For troubleshooting, PrismML suggests a generous limit such as max_tokens: 16384 and -c 65536 only where the device has sufficient RAM. The known issues also describe a macOS 27 / Xcode 26.5 build problem for setup.sh. Check the release and current issues before production use.
PrismML documents OpenAI-compatible tool_calls and optional MCP in its tool guide. This does not establish that a particular coding agent will succeed. Validate JSON and tool results, restrict tools and confirm filesystem changes.
Price and license
The model weights are available for free under Apache 2.0. 23411 We found no separate official PrismML hosted-inference price that should be treated as the Bonsai 2 price.
Alibaba Cloud does publish API pricing for the underlying qwen3.8-27b service, but that is a different hosted product and must not be presented as the price of self-hosted Bonsai 2. 13
A repeatable Apple Silicon compatibility check
Checked October 9, 2026: The PrismML demo repository and backend support matrix still require the PrismML llama.cpp fork for Bonsai 2 GGUF. A file that happens to load in upstream llama.cpp can still produce invalid outputs because the required Hadamard/sign-flip operations are missing. Loading a model is not evidence that inference is correct.
Record the demo/fork commit, exact GGUF file and digest. Compare PTQ1_0 and PQ2_0 on the same tasks and require at least one expected response to pass an automated correctness check. Collect actual peak RAM/swap, prefill rate, decode rate, Mac chip, context length and vision-projector footprint if used. PrismML’s often quoted 98.2% quality retention is a vendor-aggregated benchmark, not an independently reproduced figure or a measured Mac memory guarantee.
Who should care now?
Bonsai 2 is most compelling when the target workload needs a large local model, multimodal input or agentic behavior while weight memory is unusually constrained.
It is less compelling today if the primary requirement is frictionless compatibility with existing generic GGUF frontends.
And one question remains deliberately open: whether independent evaluations will reproduce the vendor’s unusually strong quality-per-gigabyte result across long agent runs, coding, vision and real documents.
Conclusion: Bonsai 2 as a specialist local-AI build, not a universal GGUF
The interesting part of Ternary Bonsai 2 27B is not a single “5.9 GB” number. It is the engineering trade: 27B-class Qwen3.8 behavior compressed into a 1.75-bpw shipped GGUF representation, with a 262K native context and multimodal support, at the cost of requiring a specialized runtime path today. 34
The launch looks technically credible from the primary artifacts: pack sizes are inspectable, format behavior is documented, the reference implementation is public, and benchmark methodology is described. What is still missing is mature independent validation of the headline 98.2% retention and a broad, stable ecosystem around the new GGUF types.
For a useful local-AI test, record the exact packing, runtime commit, context length, prompt-processing speed, generation speed, peak memory and task-level quality. Without those fields, “27B in 5.9 GB” is a headline; with them, it becomes a reproducible result.
How memory, quantization and context interact is explained in the unified memory guide.
References for technical claims
Links identify the original model, community, or external report backing each claim. Citation alone is not an independent performance test; runtime support can change.
Footnotes
Frequently Asked Questions
What does "ternary" mean for Bonsai 2?
Weights are mapped group-wise to three values (-1, 0, +1) with one FP16 scale per group of 128 weights. Weight matrices are additionally rotated block-wise into a Hadamard basis so the activation transform can be applied at runtime. This is why stock llama.cpp does not execute the new GGUF formats out of the box.
Are 5.9 GB the real RAM requirement?
No. 5.95 GB is the PTQ1_0 download size. Actual RAM depends on KV cache, context and runtime buffers, and this site has not measured peak usage on typical Macs. MLX contains vision weights but the 27B image pipeline is not functional per PrismML known issues.
What does the 98.2% benchmark retention actually prove?
PrismML measured a 98.2% match against the FP16 baseline in two of its own benchmark suites (20-suite aggregate and 14-suite aggregate). Both aggregates are vendor benchmarks; independent replications with the same harness are not yet published. The number is a starting point, not evidence for real workload quality.
Can I run Bonsai 2 27B on a Mac today?
Yes, using the PrismML llama.cpp fork for GGUF with the Metal backend. MLX needs its bundled loader and the 27B MLX path currently lacks working image input. No unverified Mac RAM or speed guarantees are provided.
Are Bonsai 2 inputs used for training?
Bonsai 2 weights are published under Apache 2.0, but there is no central PrismML inference-API product with a documented retention policy. If you need a training opt-out, lock it down contractually with the runtime operator or third-party API provider.
Where are the primary technical sources for these numbers?
The primary technical sources are the three Hugging Face model cards (PTQ1_0 GGUF, PQ2_0 GGUF, MLX), the PrismML llama.cpp fork repository, and the upstream llama.cpp issue. Benchmark numbers come from the PrismML benchmark-suite repo and are explicitly labeled as vendor results.