Original 26.9 research checked September 18, 2026; updated October 10, 2026. Vendor results and illustrative calculations are identified. The preview is verified against the Unbiased release announcement and the separate OpenRouter model listings; the general Unbiased pricing page currently publishes different API rates.
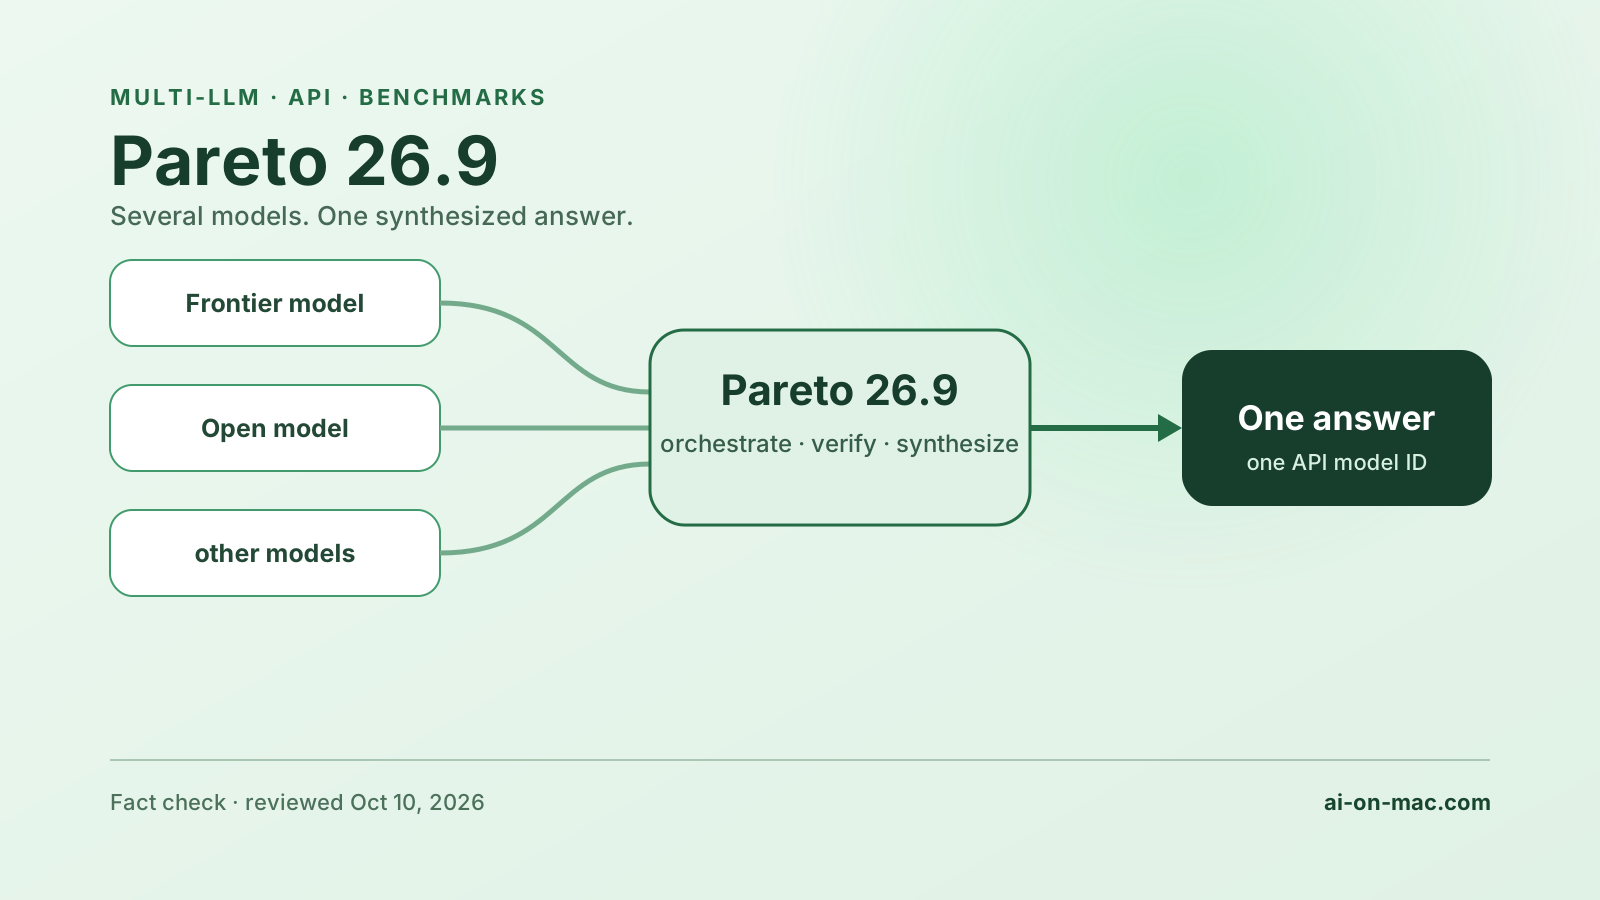
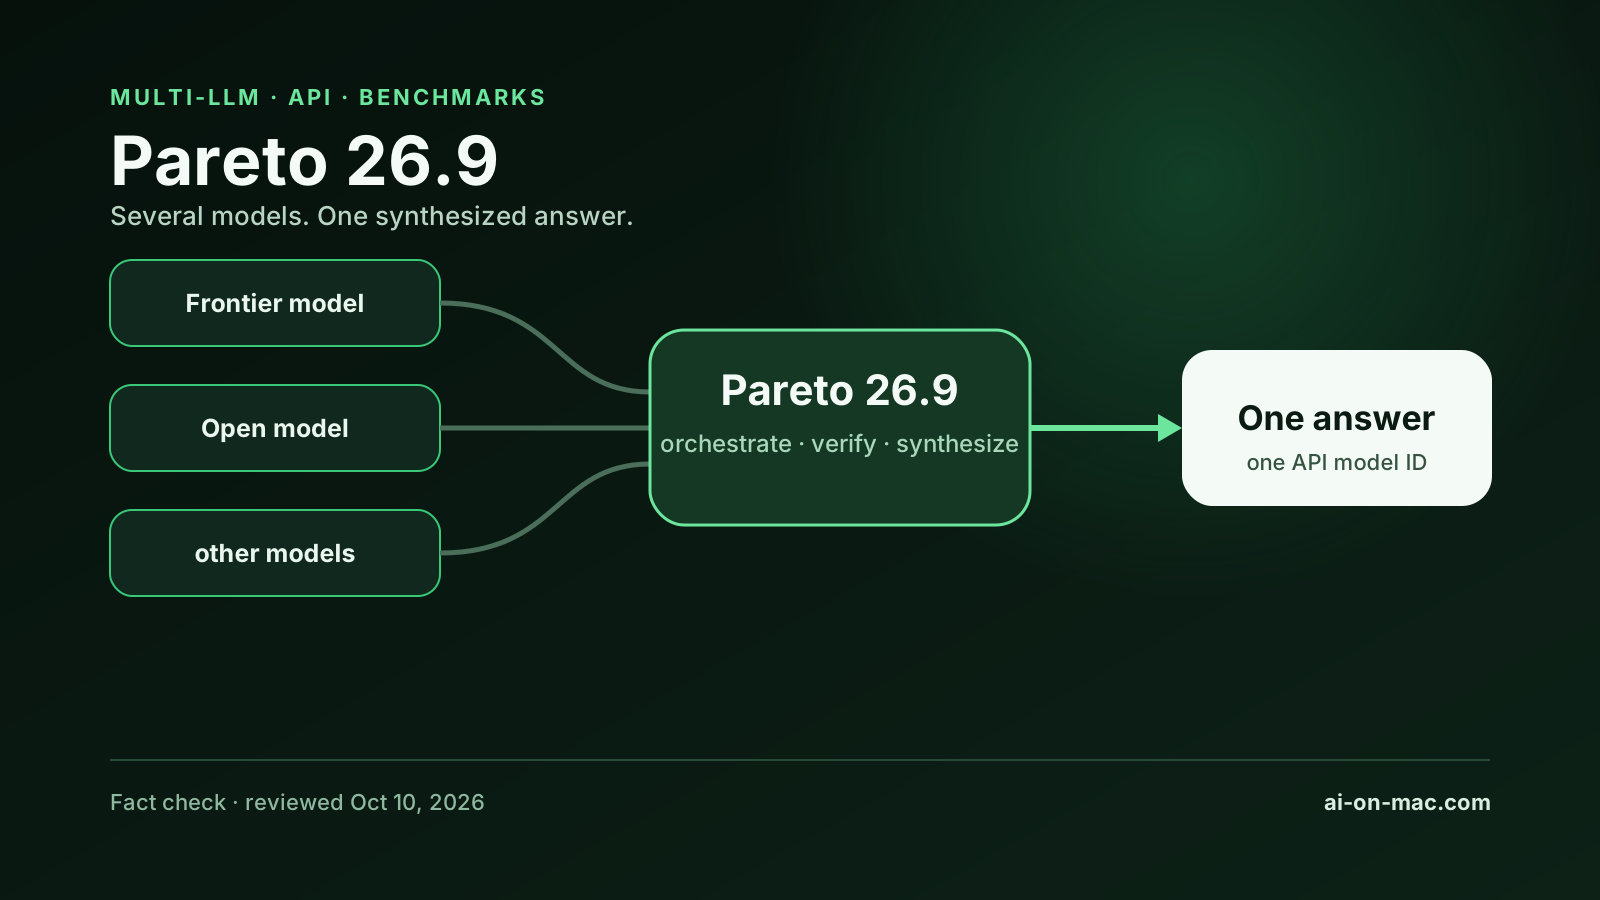
At API level, Pareto 26.9 behaves like a model: select pareto, send a request, receive an answer. Underneath that interface, however, Pareto is not a conventional standalone foundation model with one published set of weights.
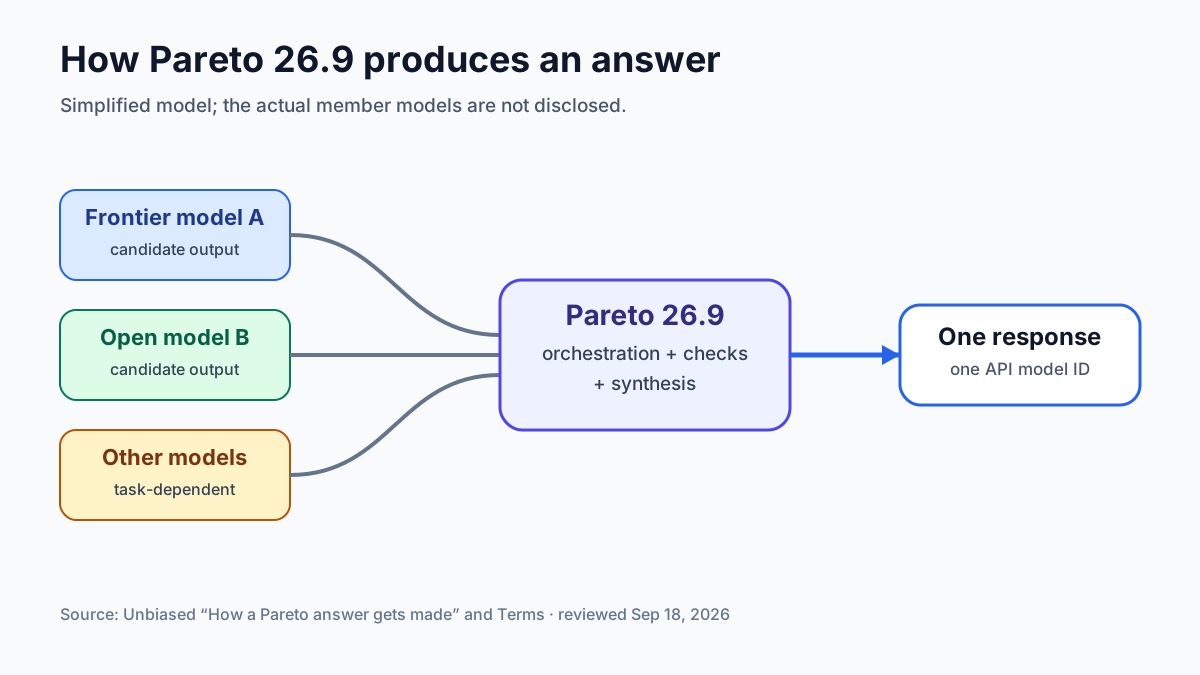
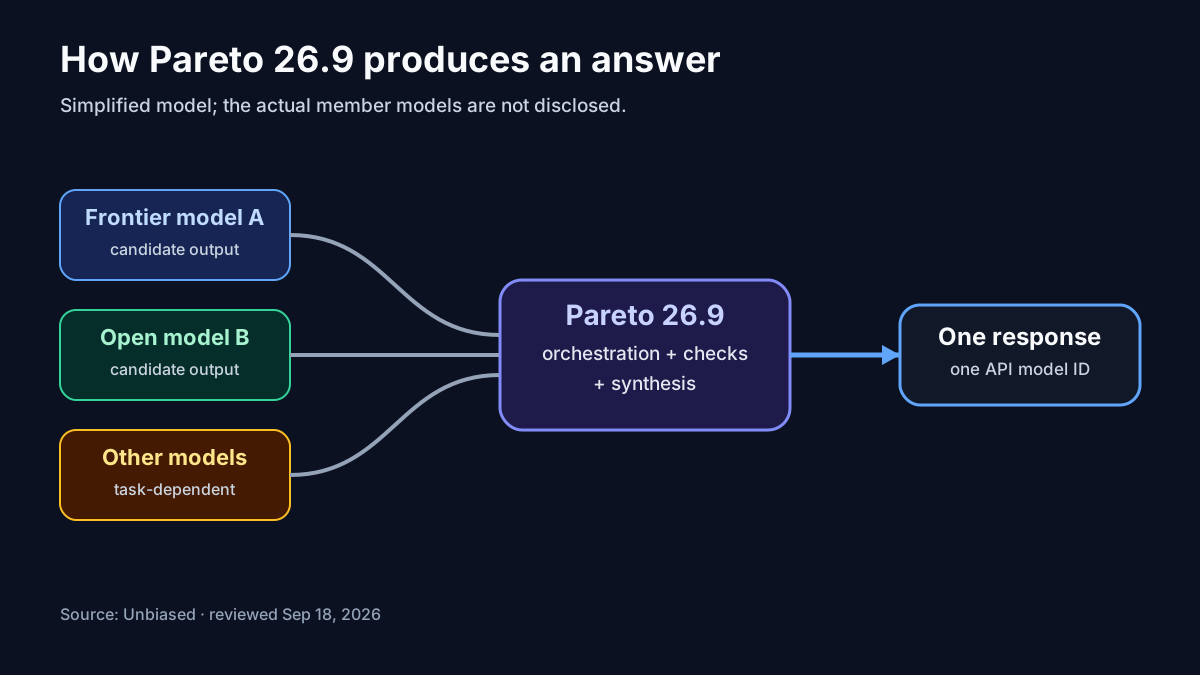
Unbiased defines Pareto as a proprietary blended AI system. Multiple underlying LLMs contribute outputs that are synthesized into a single response. The same description appears both in the technical explanation and in the company’s terms, making this more than a loose marketing analogy. (Unbiased)
The September 26.9 rate card was $2.50 per million input tokens, $0.25 per million cached-input tokens and $7.50 per million output tokens. Those numbers matter because older pages still expose the considerably lower Pareto 26.8 rates. (Unbiased)
There is an equally important benchmark caveat. Unbiased has published five scores for 26.9, and the evaluation harness is public, but there is not yet a complete independent reproduction of those Pareto runs. Unbiased also says that measured cost per benchmark task and a composite score have not been published for 26.9. (GitHub)
October 10, 2026: 26.9 and 26.10 are separate API listings
OpenRouter IDs are not interchangeable. unbiased/pareto is the 26.9 listing (262,144 context tokens); unbiased/pareto-26.10-preview is a separate preview listing (1,048,576 context tokens). Do not infer model selection from an alias. 26.9 listing · Preview listing.
| OpenRouter version | Input / 1M | Cached input / 1M | Output / 1M |
|---|---|---|---|
26.9 (unbiased/pareto) | $2.50 | $0.25 | $7.50 |
26.10 Preview (unbiased/pareto-26.10-preview) | $0.80 | $0.03 | $3.20 |
Documentation inconsistency: The general Unbiased pricing page still shows 26.9 pay-as-you-go rates, while the October 1 preview post shows the lower 26.10 rates. These preview rates must not be assumed for all direct-provider API requests. Unbiased’s direct API documents pareto as its model ID, distinct from OpenRouter IDs.
Preliminary vendor-reported 26.10 Preview benchmark results include GPQA-Diamond 92.4%, HLE text-only 49.9%, DeepSWE v1.1 69.9% and Terminal-Bench 4.0 50.8%. The 26.9 charts and costs below are historical reference points, not an independent 26.10 evaluation.
Pareto 26.10 Preview API limitations (October 8, 2026)
The current OpenRouter listing exposes 1,048,576 context tokens, 131,072 maximum output tokens, text/image input and tool calling. It supports tools and tool_choice, but does not support response_format for enforced JSON outputs. Agents that require a strict JSON schema should validate the response themselves and handle parse failures; an OpenAI-compatible endpoint does not automatically provide all OpenAI API features.
The October 1 Unbiased release post still describes 26.10 as a preview. OpenRouter recommends 26.9 when stable behavior matters. Do not silently carry the preview’s context, prices or output cap back to historical 26.9 benchmarks or usage examples.
For U.S. customers, the 26.10 rate card lists $0.80 ordinary input, $0.03 cached input and $3.20 output per million tokens. These are API rates, not unlimited subscriptions; applicable sales tax may be added according to jurisdiction. Unbiased’s current subscription page still lists Personal at $10/month with 25 million tokens per week and Personal Max at $100/month with 300 million tokens per week. The higher weekly allowances announced for the eventual stable 26.10 release are not yet in effect just because the preview is available. Keep account quotas, request-per-minute limits and any third-party gateway bill separate.
Pareto 26.9 at a glance
| Field | Current information |
|---|---|
| Provider | Unbiased / Circuit & Chisel |
| Product type | proprietary blended / multi-LLM system |
| Direct model ID | pareto |
| OpenRouter model ID | unbiased/pareto |
| Inputs | text and images |
| Output | text, according to OpenRouter |
| Input price | $2.50 / 1M tokens |
| Cached input | $0.25 / 1M tokens |
| Output price | $7.50 / 1M tokens |
| Context | 262,144 tokens reported by OpenRouter |
| Published Pareto weights | none |
| Public 26.9 benchmark scores | five |
| Evidence date | September 18, 2026 |
One source distinction is worth preserving: OpenRouter reports the 262,144-token window for Union Alpha/Pareto, while Unbiased’s current 26.9 model card does not publish a context-window figure. It is therefore safer to call 262K an OpenRouter-reported specification, rather than a first-party Unbiased spec. (OpenRouter)
Union Alpha was the stealth launch
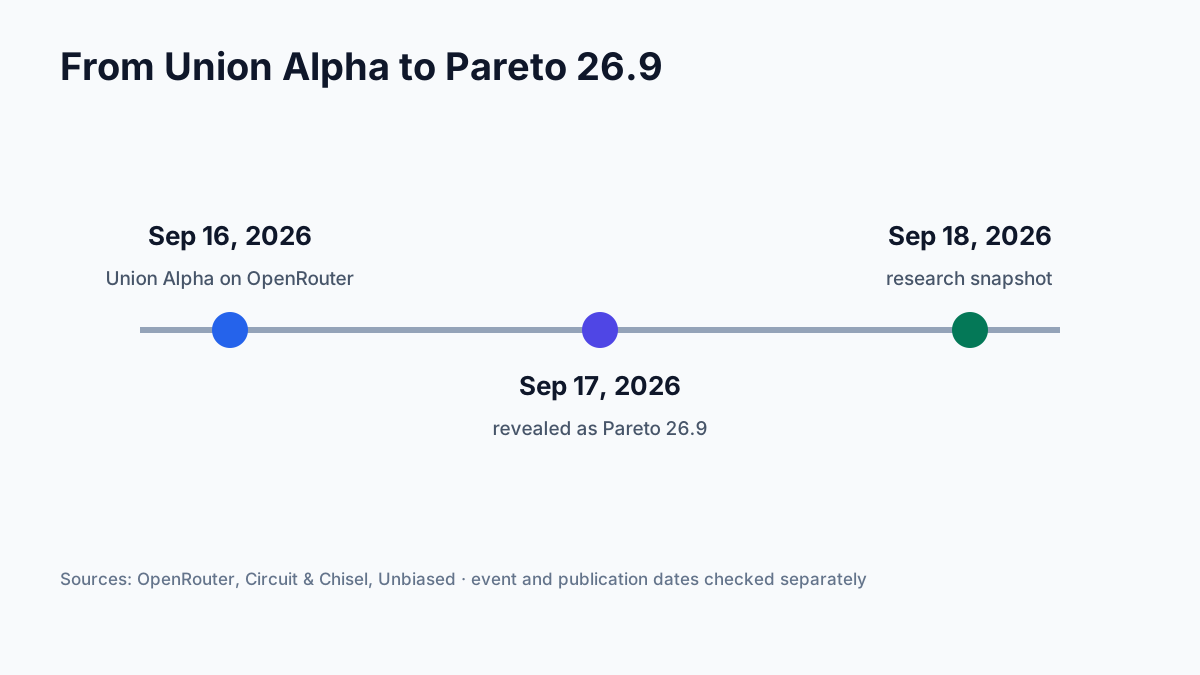
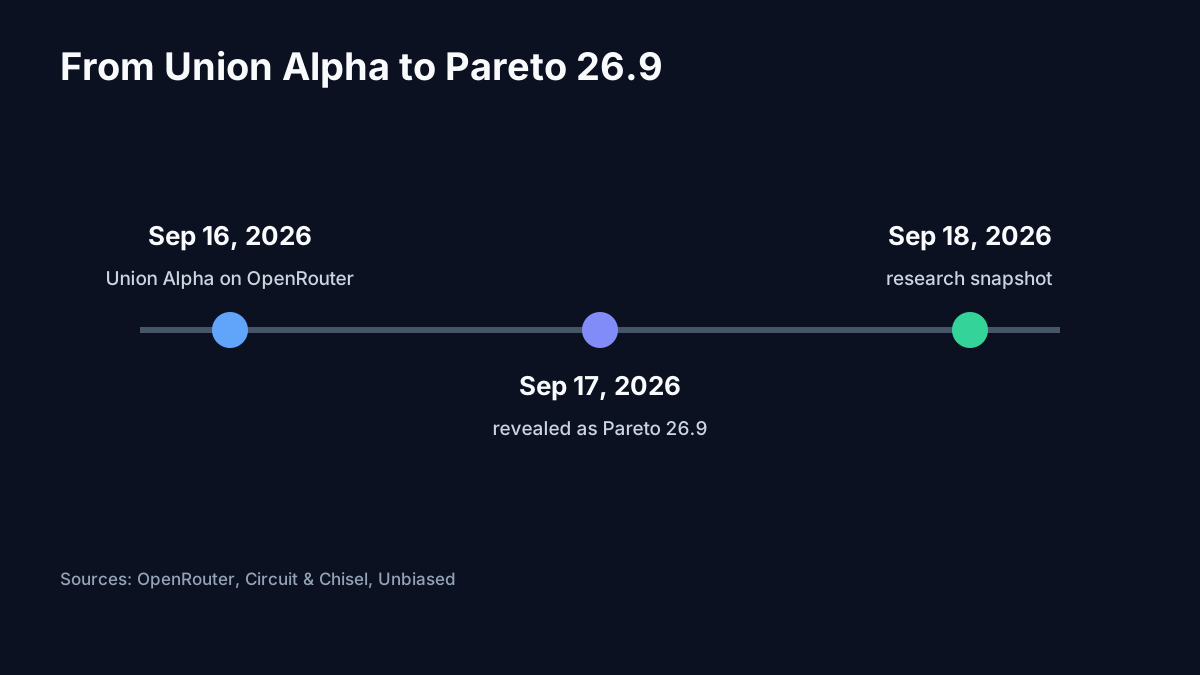
OpenRouter says Union Alpha launched on September 16, 2026 and was subsequently revealed to be Pareto by Unbiased. The platform now states this directly rather than leaving the developer anonymous. (OpenRouter)
That stealth period generated a burst of reverse engineering. Community researchers compared response IDs, infrastructure fingerprints and tokenizer behavior before the official identity was public. Those observations are useful history, but they should no longer be treated as the primary evidence for the identity of the model, which the provider now confirms. (YFarmX)
For a durable reference page, “Union Alpha” is therefore best treated as Pareto 26.9’s launch alias, not as a separate current model.
A blend is different from a conventional router
A conventional model router classifies a request and then chooses one model to handle it. Unbiased says Pareto instead engages multiple LLMs on each request and synthesizes their work. Its blend includes both frontier and open models. (Unbiased)
The company’s terms are even more explicit: Pareto combines outputs from multiple underlying large language models, accessed through Unbiased’s own provider arrangements, and synthesizes them into one response. (Unbiased)
Calling Pareto “not a router” is therefore useful only if “router” means a system that selects one downstream model and forwards the request. A more neutral technical label is an inference ensemble or orchestration layer presented as a model endpoint.
The underlying member models are not disclosed. That prevents users from assigning Pareto’s score, latency or failure pattern to any single base model.
26.9 changed the economics
Pareto 26.8 was published at $1.25 input, $0.15 cached input and $6.25 output per million tokens. The 26.9 card lists $2.50/$0.25/$7.50. The separate October 1 preview release lists $0.80/$0.03/$3.20 for 26.10 Preview, although the generic pricing page still shows 26.9 rates. State the version alongside each price.
The version-to-version change is therefore:
| Token class | 26.8 | 26.9 | Change |
|---|---|---|---|
| Input | $1.25 | $2.50 | +100% |
| Cached input | $0.15 | $0.25 | +66.7% |
| Output | $6.25 | $7.50 | +20% |
These percentages are our calculations from the published rate cards.
The distinction matters beyond list price. Older Pareto material contains attractive measured dollars-per-task figures for 26.8. Those numbers should not be recycled as 26.9 performance claims. Unbiased explicitly states that measured task costs and a composite score have not yet been published for the new release. (Unbiased)
Three example monthly bills
Historical 26.9 rates (not the preview):
Cost (26.9 card, September 18) = uncached input MTok × $2.50 + cached input MTok × $0.25 + output MTok × $7.50
For the 26.10 Preview, the rate above ($0.80 / $0.03 / $3.20) applies instead. The examples below deliberately stay on the 26.9 card so the arithmetic stays checkable against the September pricing.
For the same medium workload, the 26.10 Preview list-rate calculation is 12M × $0.80 + 8M cached × $0.03 + 5M output × $3.20 = $25.84 instead of the historical 26.9 $69.50. Cache eligibility and direct API billing must be checked separately.
Our illustrative calculations:
| Usage profile | Uncached input | Cached input | Output | Cost |
|---|---|---|---|---|
| Light | 2M | 0 | 0.5M | $8.75 |
| Medium | 12M | 8M | 5M | $69.50 |
| Heavy | 80M | 120M | 50M | $605.00 |
The medium case is $30 + $2 + $37.50. Without the assumed cache hits, the same 20M input tokens would cost $50 and the total would be $87.50.
The heavy case is $200 + $30 + $375. Without cached input it would be $875.
These are not billing predictions. Real cache eligibility depends on request structure and usage. Unbiased’s terms also state that fees are exclusive of applicable taxes unless the invoice specifies otherwise. (Unbiased)


Direct access currently uses prepaid credits, and Unbiased says new accounts are manually reviewed before API access is enabled. Credits are generally non-refundable and non-transferable and do not expire unless an order form says otherwise. (Unbiased)
The five published benchmark scores
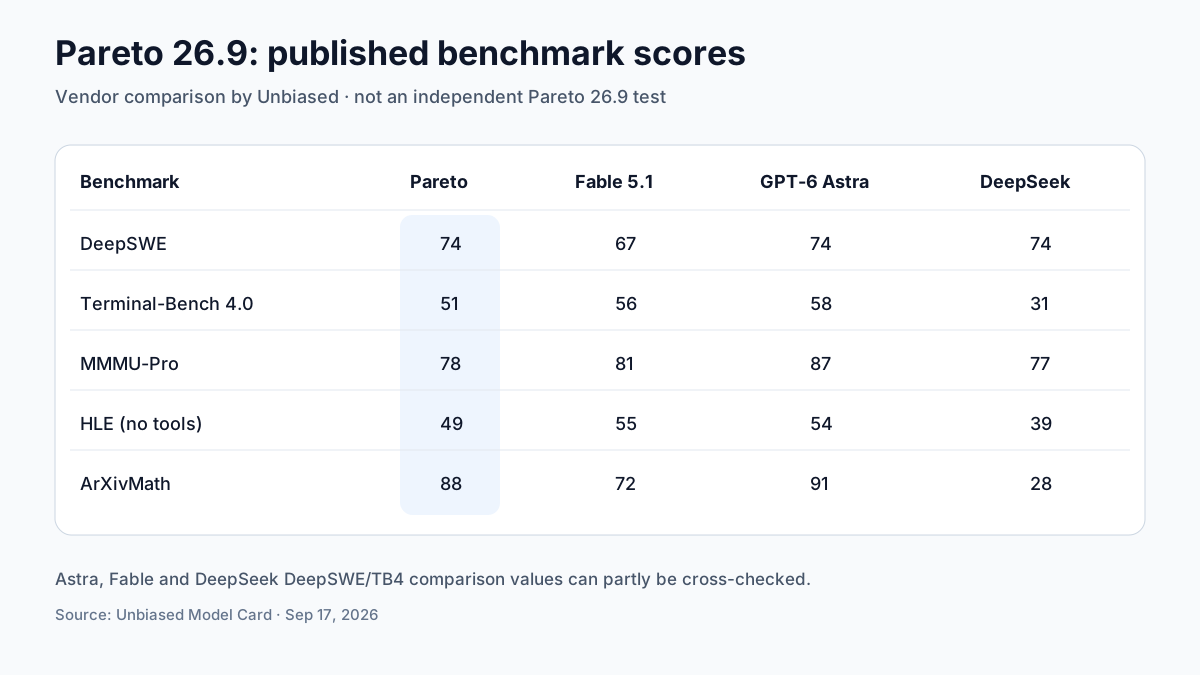
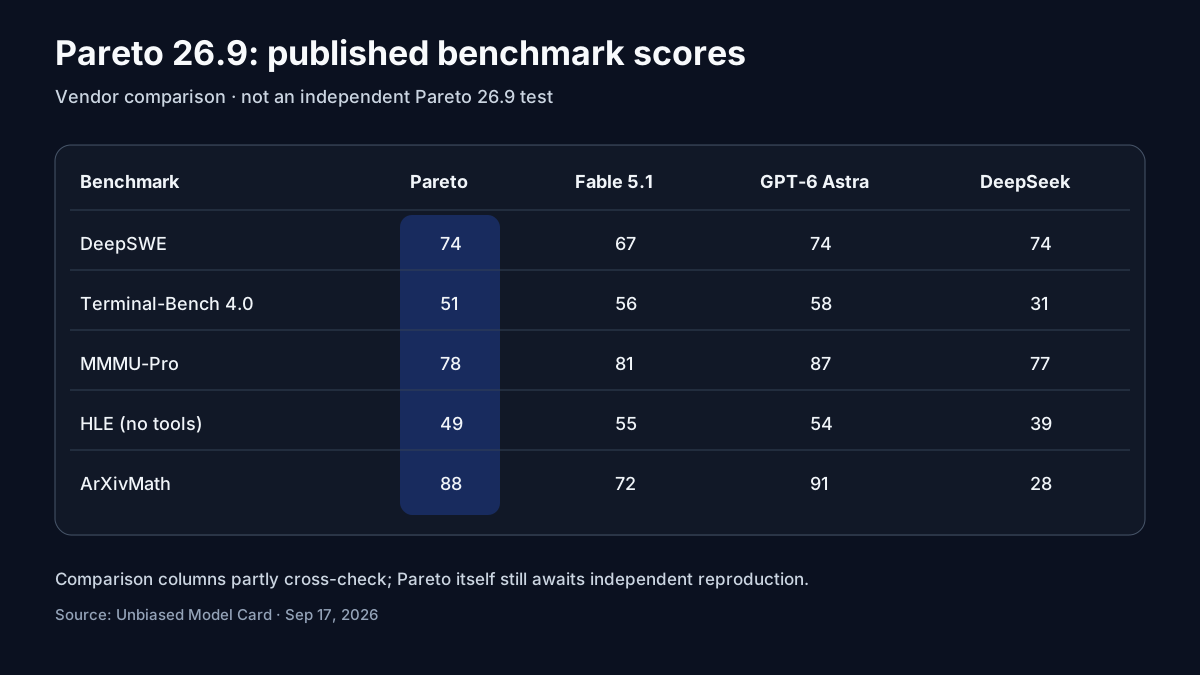
Unbiased currently shows:
| Benchmark | Pareto 26.9 | Fable 5.1 | GPT-6 Astra | DeepSeek 4.1 Flash |
|---|---|---|---|---|
| DeepSWE | 74 | 67 | 74 | 74 |
| Terminal-Bench 4.0 | 51 | 56 | 58 | 31 |
| MMMU-Pro | 78 | 81 | 87 | 77 |
| HLE, no tools | 49 | 55 | 54 | 39 |
| ArXivMath | 88 | 72 | 91 | 28 |
This is a vendor-published comparison table. It should not be presented as an independent benchmark. (Unbiased)
For deeper context on the comparison models, see our separate source checks for GPT-6 Astra, Claude Fable 5.1 and DeepSeek V4.1 Flash.
Still, several comparison numbers cross-check unusually well. OpenAI reports 57.9% for GPT-6 Astra on Terminal-Bench 4.0 and 74.1% on DeepSWE v1.1; the same OpenAI table gives Claude Fable 5.1 55.8% and 67.4%. Those values round to the 58/74 and 56/67 in Unbiased’s table. (OpenAI)
DeepSeek independently reports 31.2% for V4.1 Flash on Terminal-Bench 4.0 and 74.2% on DeepSWE v1.1, again matching Unbiased’s rounded comparison values. (DeepSeek API-Dokumentation)
That gives the comparison columns useful corroboration. It does not independently establish Pareto’s own 51 and 74.
One HLE discrepancy explains why methodology matters
Unbiased’s table assigns Fable 5.1 a score of 55 on HLE without tools. Anthropic’s own Fable 5.1 publication reports 60.9% no-tools under its evaluation setup. (Unbiased)
This is not enough evidence to call either number wrong. Effort settings, prompts, judges and dataset details can all change a result. It does demonstrate why benchmark names alone are not sufficient for apples-to-apples comparisons.
The datasets themselves also evolve. MMMU-Pro corrected ground-truth labels as recently as July 10, 2026 and had previously fixed an option-augmentation issue. (Hugging Face)
DeepSWE v1.1 contains 113 tasks in the Pareto harness. A July independent audit reran every reference solution and found that 112 of 113 passed their own verifier, leaving one broken reference case. (GitHub)
Humanity’s Last Exam contains 2,500 expert-created questions across many fields and publishes a dataset canary intended to help future model developers exclude the material from training. (GitHub)
The right interpretation is therefore not “Pareto wins benchmark X.” The defensible statement is that Unbiased’s own evaluation places Pareto 26.9 near current frontier systems on several heterogeneous tests, while independent Pareto reproduction is still missing.
The public harness improves auditability
Circuit & Chisel publishes pareto-evals under the MIT license. It is designed for head-to-head evaluation through OpenAI-compatible endpoints and records accuracy plus cost per completed task. The repository explicitly says it does not track latency. (GitHub)
The agentic slate currently identifies DeepSWE v1.1 as 113 tasks and Terminal-Bench 4.0 as 66 tasks. API-based runs do not require a local GPU. (GitHub)
That makes Pareto unusually easy to challenge using its maker’s own tooling. A serious buyer should do exactly that: run both public benchmarks and an internal task set against Pareto and the incumbent model.
Latency is the biggest open operational question
There is no current independent Pareto 26.9 latency study in the evidence reviewed here.
Unbiased’s September 16 changelog nevertheless reveals a practical constraint. Non-streaming Pareto requests had their timeout increased from 120 to 300 seconds after long completions (typically 60 to 110 seconds) were hitting the old ceiling on roughly 13% of those requests. Streaming requests were unaffected. (Unbiased)
That is operational telemetry, not a benchmark. But it is enough to make latency a mandatory part of any production trial.
Official API endpoint and a reproducible smoke test
The official developer docs specify https://api.unbiased.ai/v1 with direct model ID pareto. They document OpenAI-compatible /chat/completions and Anthropic-compatible /messages endpoints. Direct API access requires a provider-issued key.
curl --fail-with-body -sS https://api.unbiased.ai/v1/chat/completions \
  -H "Authorization: Bearer $UNBIASED_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{"model":"pareto","messages":[{"role":"user","content":"Explain KV-cache eviction briefly."}]}'
Compatibility caveat: Unbiased says GET /v1/models is not implemented and unknown IDs may still be processed and billed as Pareto. Do not test preview selection by inventing a model name. Use unbiased/pareto-26.10-preview only on OpenRouter’s separate API, then verify the endpoint and costs. HTTP 429 signals a rate limit; the changelog lists server tools but does not guarantee tool support in every client.
Unbiased Chat: new since October 9, and not ZDR
Unbiased Chat launched on October 9, 2026 for Personal ($10/month, 25M tokens per week) and Personal Max ($100/month, 300M tokens per week). These are limited weekly allowances. Chat is included in these subscriptions, while pay-as-you-go API credits alone do not unlock Chat.
Unlike the separate zero-data-retention API tier, Chat saves conversations and Projects. The subscription therefore does not establish ZDR for sensitive files. Web search and image generation also run as hosted tools rather than on the Mac. Check the data policy and the actual processing route.
Privacy: read the terms, not just the launch posts
The current terms provide a relatively clear position:
Customer content is retained only as reasonably necessary to process a request, with an exception for legal requirements, abuse prevention and security monitoring of up to 30 days. Unbiased also says it will not use customer content to train, fine-tune or improve a model without explicit written consent. (Unbiased)
The terms additionally assign customers ownership of their inputs and outputs as between the customer and Unbiased. (Unbiased)
So the accurate shorthand is “no training on customer content without explicit consent”, not “guaranteed instant deletion under every circumstance.”
Where customers use BYOK access to third-party providers, those providers’ own data terms apply as well. (Unbiased)
Can Pareto run locally on Apple Silicon?
Not as a released Pareto 26.9 package.
There are no published Pareto weights, MLX files or documented Ollama/llama.cpp distribution. Unbiased says the internal blend includes open models, but Pareto’s product value lies in its proprietary multi-model orchestration. (Unbiased)
A Mac can therefore use Pareto very comfortably as an API client, but Apple Silicon does not perform the Pareto inference locally. Unified memory, quantization and Metal throughput matter for self-hosted open-weight models; they do not determine the performance of a remote Pareto request.
If you want to run models locally instead, the Unified Memory guide explains how weights, quantization and KV cache translate into Apple-silicon memory requirements.
For Mac developers, the useful comparison is consequently not “How much RAM does Pareto need?” but “When should I call Pareto instead of running a local MLX model?” The answer depends on privacy requirements, offline availability, latency, task difficulty and API spend.
Frequently Asked Questions
Is Pareto 26.9 a standalone LLM?
Not in the usual sense of a single published checkpoint. Unbiased describes Pareto as a proprietary blended system that engages multiple LLMs per request and synthesises their outputs into one response.
Which models power Pareto 26.9?
Unbiased does not publish a full list of member models. The provider only states that the blend includes frontier and open models and that the composition may change over time.
How much does unbiased/pareto cost?
OpenRouter lists unbiased/pareto (26.9) at $2.50/$0.25/$7.50 per 1M input/cached/output tokens and the distinct unbiased/pareto-26.10-preview at $0.80/$0.03/$3.20. The generic Unbiased pricing page still lists 26.9 rates; confirm the exact provider and model version.
Does Pareto 26.9 have a 262K context window?
For 26.9, OpenRouter reports 262,144 tokens. The listed 26.10 Preview reports 1,048,576 tokens of context, so the window depends on the version. Both figures are provider-reported rather than first-party Unbiased model-card specs.
Can Pareto run locally on a Mac?
Not as a published Pareto 26.9 checkpoint. There are no official Pareto weights for MLX, Ollama or llama.cpp; on a Mac, Pareto is currently consumed as a cloud API.
Are prompts used for training?
According to the current Unbiased terms, customer content is not used to train, fine-tune or improve models without explicit written consent. The terms permit a retention of up to 30 days for abuse prevention and security monitoring.
What is Pareto 26.10 Preview?
An identifier listed on OpenRouter since October 1, 2026 (unbiased/pareto-26.10-preview) with 1,048,576 tokens of context and $0.80/$3.20 per 1M tokens. Unbiased publishes preliminary scores on four benchmarks for it; a composite score and independent reproduction are still missing.
Does Unbiased Chat use zero data retention?
No. Chat saves conversations and Projects. It is included in Personal and Personal Max, not in prepaid API credits alone. The ZDR API tier is separate.
Transparency
Sources and review basis
These primary and reference sources form the basis of the technical assessment. Vendor claims and external benchmarks are identified as such in the article.
- unbiased.ai model-card
- unbiased.ai pricing
- unbiased.ai blog / pareto-26-10-preview
- unbiased.ai how
- unbiased.ai terms
- unbiased.ai changelog
- unbiased.ai developers
- unbiased.ai blog / unbiased-chat
- unbiased.ai faq
- openrouter.ai stealth / union-alpha
- openrouter.ai unbiased / pareto
- openrouter.ai unbiased / pareto-26.10-preview
- github.com circuitandchisel / pareto-evals
- openai.com index / gpt-6-astra
- deepseek.com news / deepseek-v4-1-flash
- github.com centerforaisafety / hle
- huggingface.co MMMU / MMMU_Pro
- tbench.ai run